One-Shot Skill DIY with GLOW
Task-centric spatiotemporal encoding turns one demonstration into reusable skill context. GLOW conditions action generation on this context and the current scene.
Observe Once
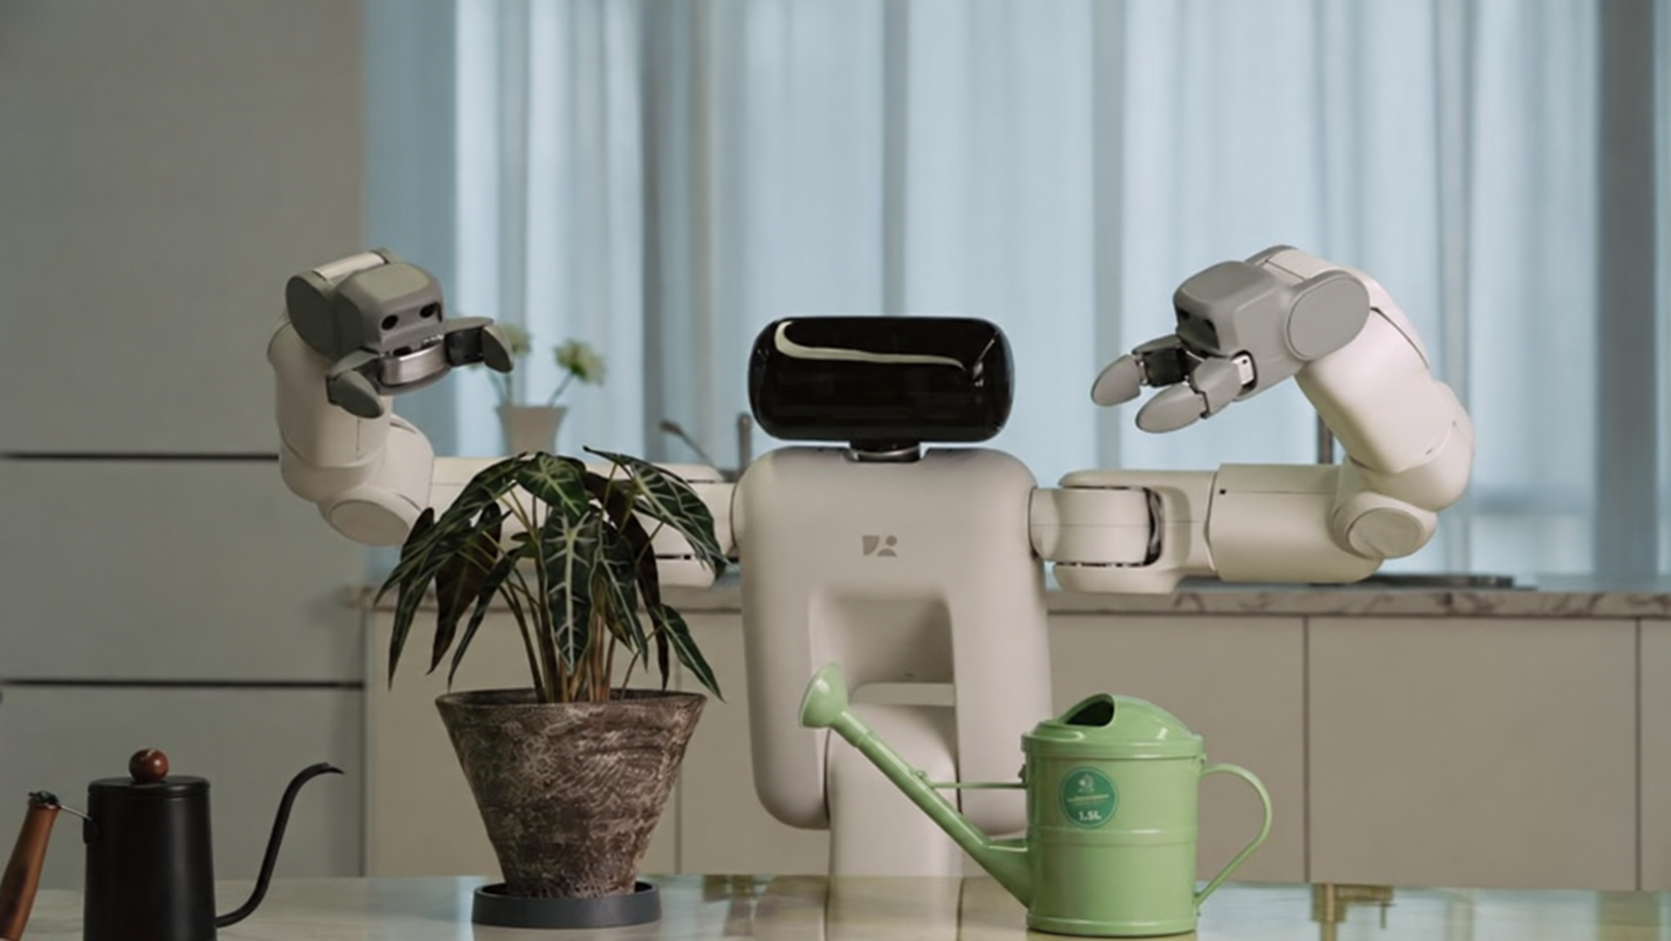
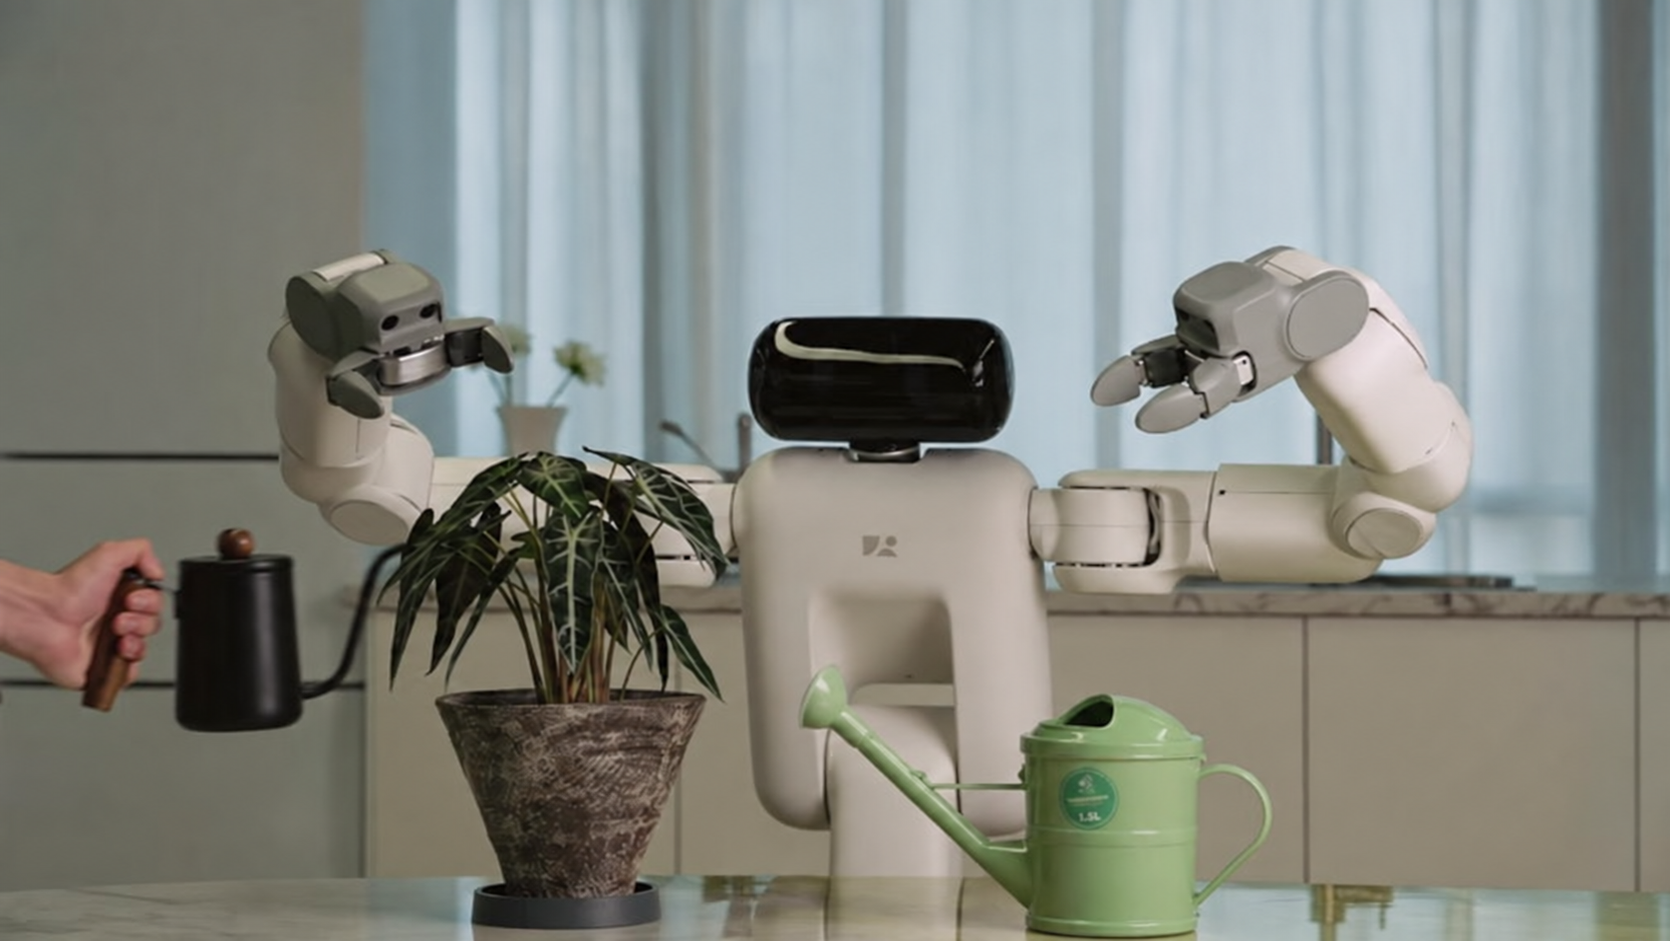
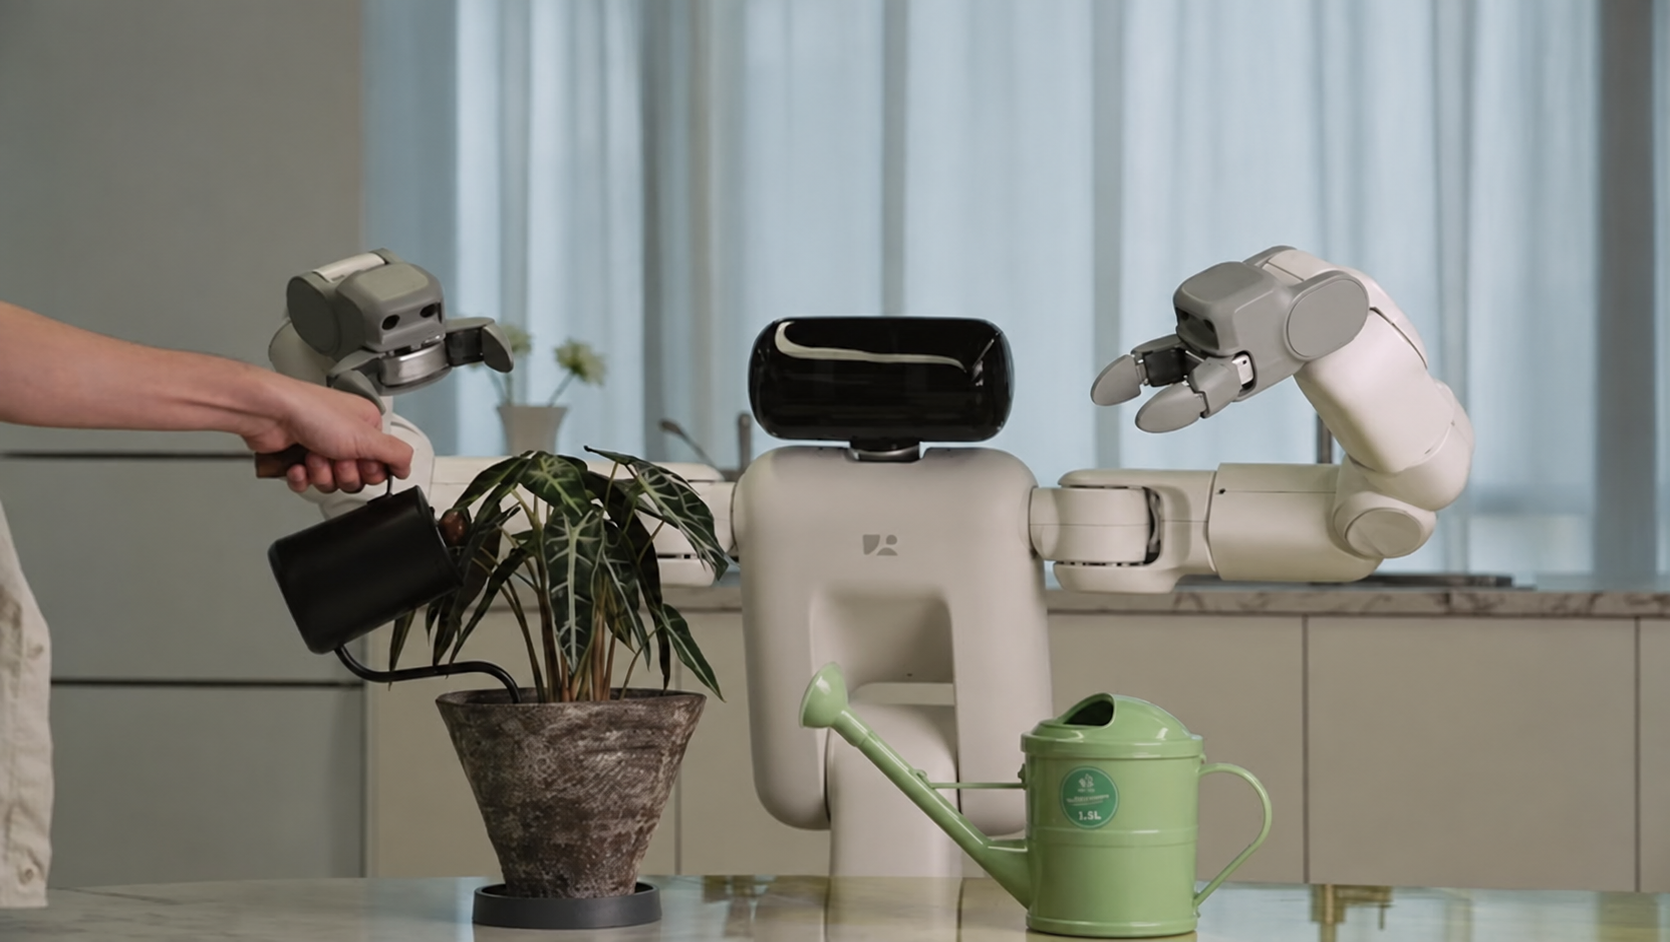
A continuous visual experience
Physical Understanding
Understand objects, interactions, and state changes jointly across frames.
Reusable Skill Context
From a DIY demonstration
Reusable skill context
CDReuse task intent and interaction knowledge as objects and scene conditions change.
Context Conditioning
Ground the skill in the current scene
Reuse the demonstrated task intent;
combine it with current execution conditions.
“Aim at the plant, then pour slowly.”
Refine goals or execution style through language.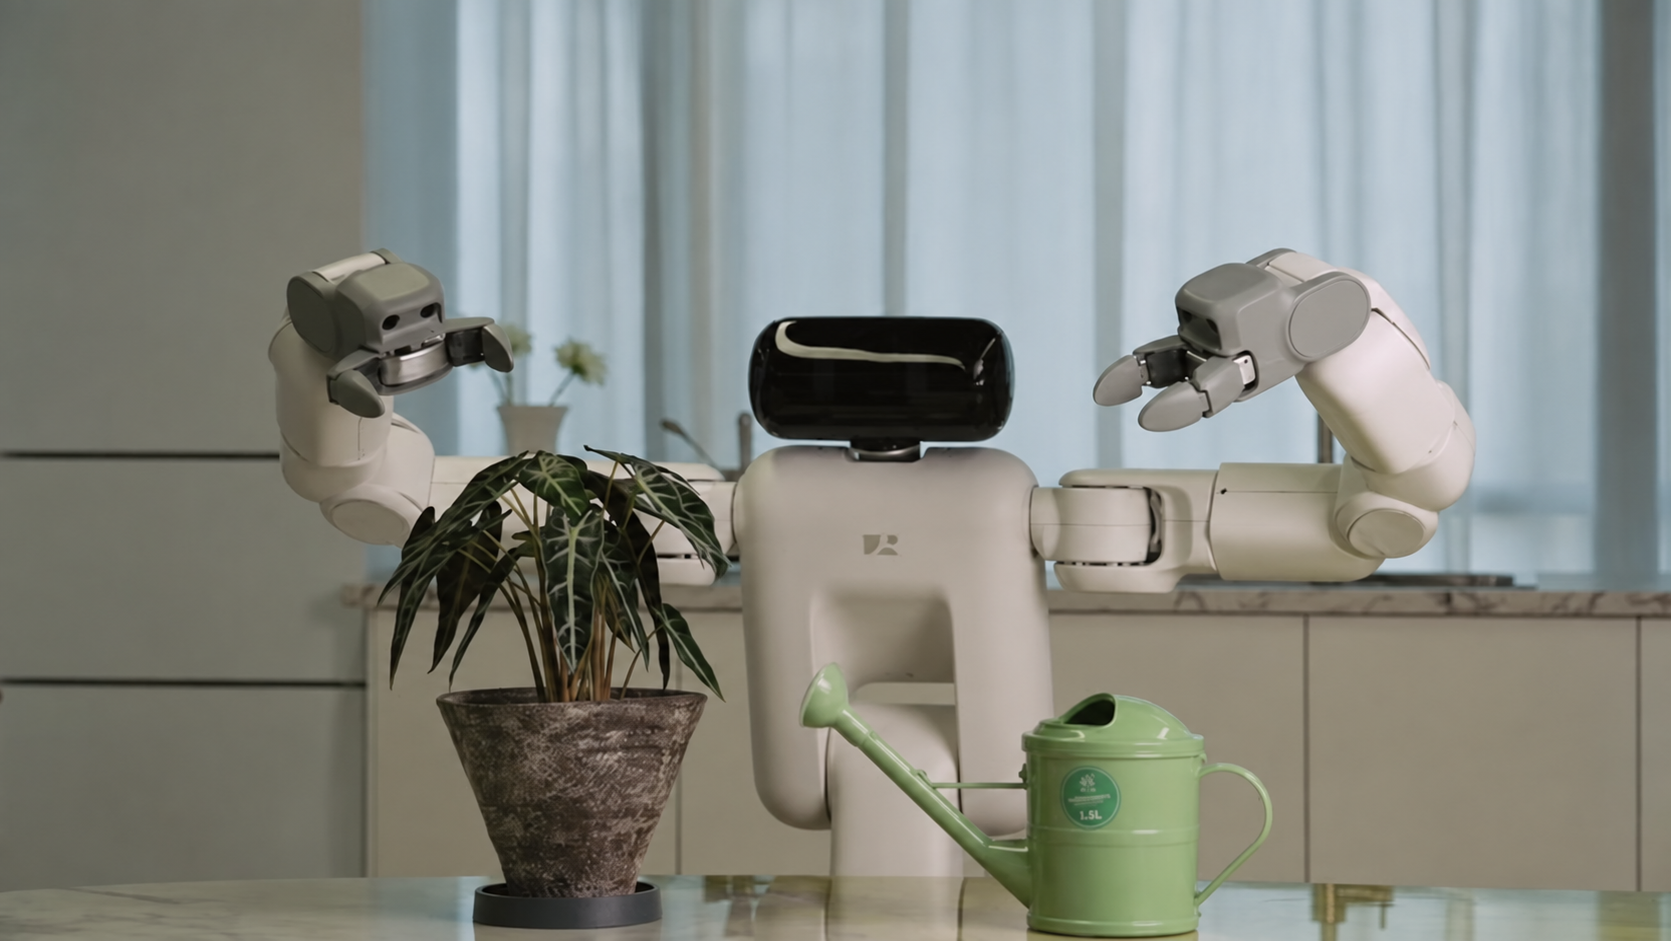
GLOW
Unified multimodal autoregressive model
Reasoning
Token
CoT-aligned task intent guides scene-dependent action.
Generate scene-dependent actions from reusable task context.
Adapt to the task through context; keep model weights fixed.
Execute & Generalize
Task-consistent, scene-adaptive actions
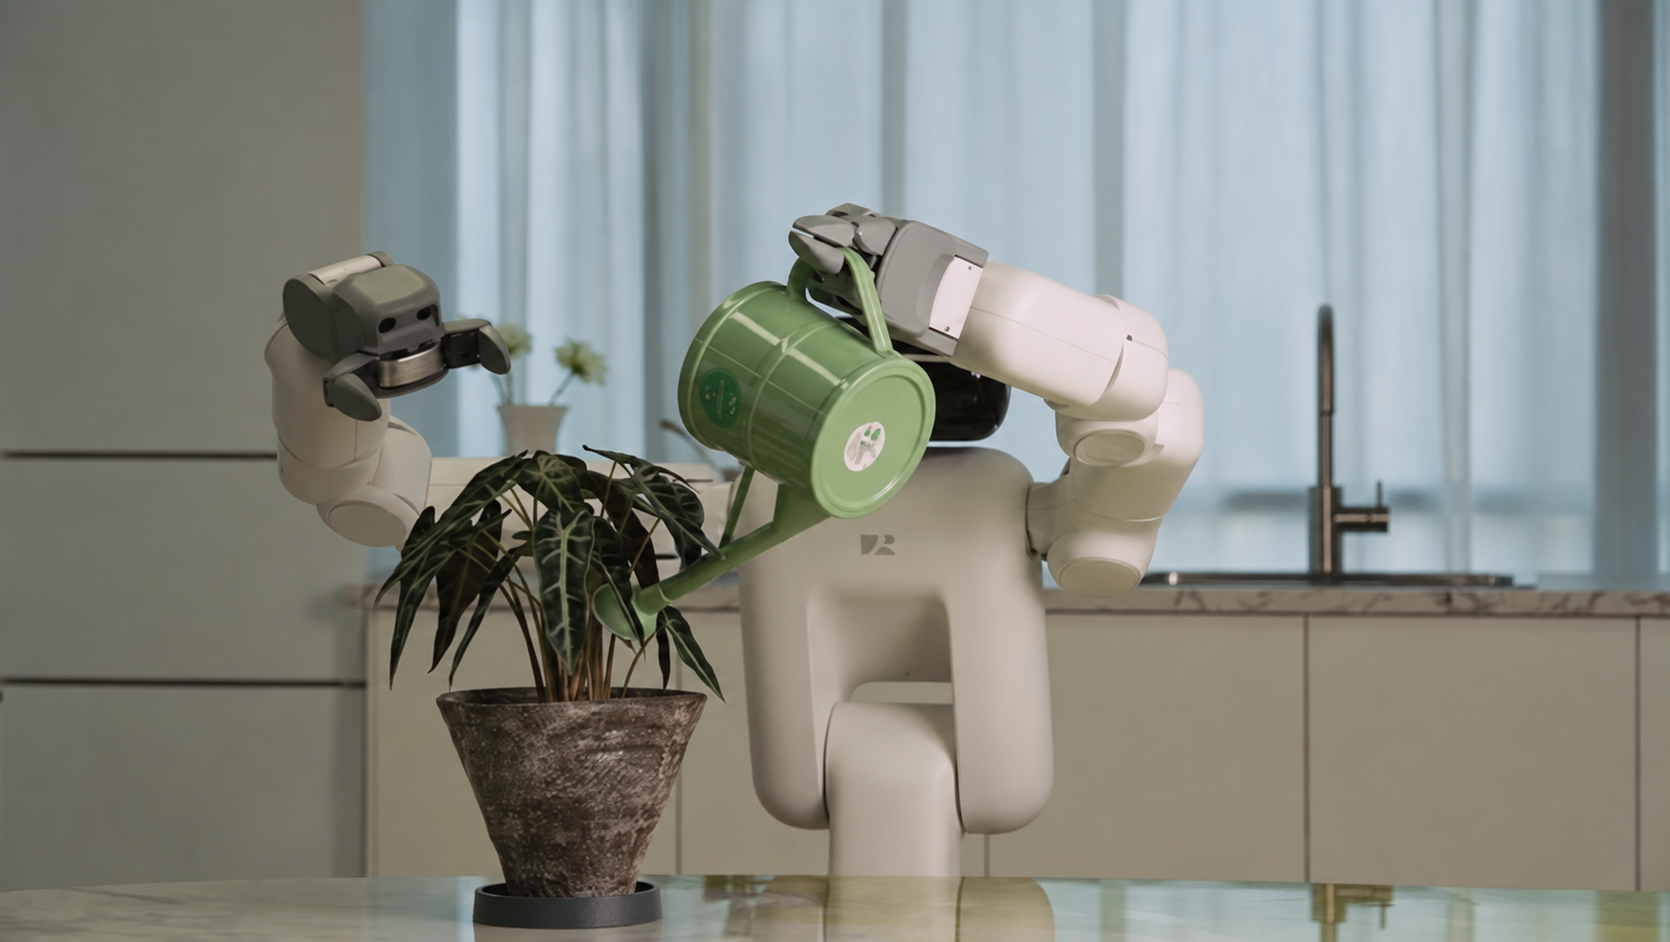
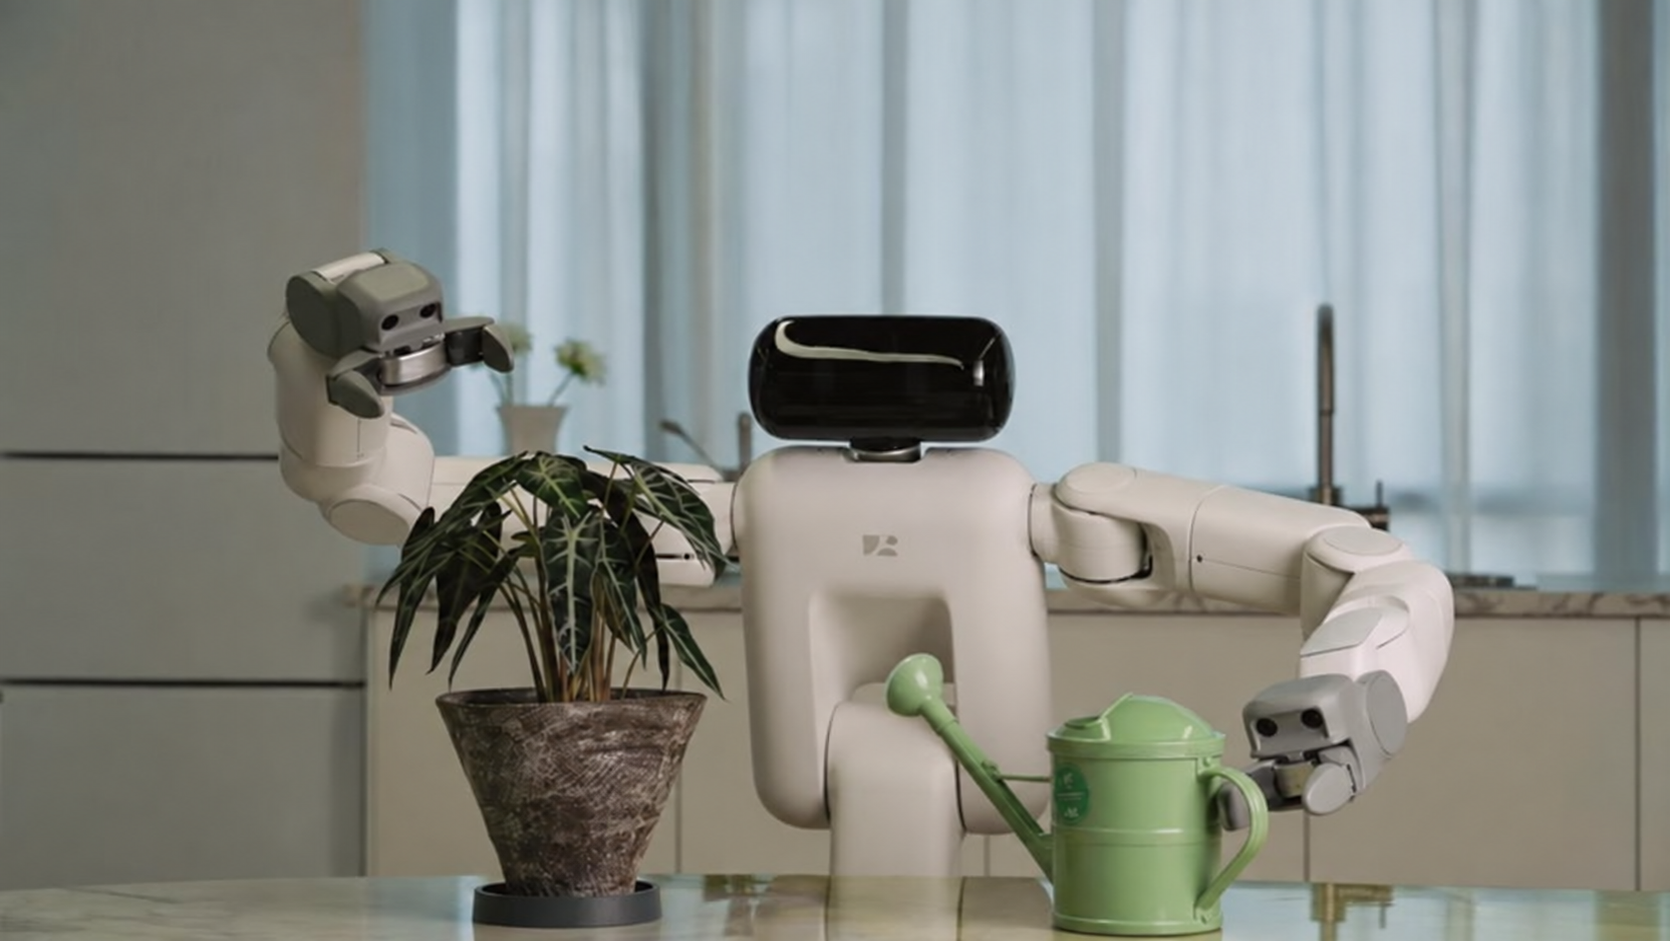
Object Generalization
Black kettle → Green watering can
Task intent transfers across objects.
No trajectory replay
GENERALIZATION THROUGH CONTEXT
Task knowledge is reused; actions are generated for the current scene.
Same Skill Context
CDReusable task intentPhysical interaction knowledge
Different Objects
OtCurrent scene + language requirements
Adapted Actions
atScene-dependent action generation · Task intent carried into execution
In-context adaptation · Fixed model weights